Retrieval-augmented generation lets an AI assistant answer from your organisation's own documents and show its sources. How it works, what decides its quality, where it fails and when it fits.
Ask a general-purpose AI assistant that cannot see your files about your leave policy or admissions rules, and at best it says it does not know or offers generic advice; at worst it gives a confident answer that sounds right but is not. Retrieval-augmented generation (RAG) is a widely used way to reduce this: the assistant looks up relevant passages in your own documents and answers from them, with sources.
Why a language model does not know your documents
A large language model learns from a vast body of text gathered up to a fixed date. Internal policies, contracts and manuals were never part of it, and anything written since is missing too. Asked about them, a model may invent a plausible answer, often called a hallucination; our plain-language guide to large language models explains why.
Fine-tuning (further training a model on your own examples) can help with tone or format once better prompts have been tried, but not with knowledge that changes: each update needs retraining, a withdrawn document cannot reliably be removed, and the model cannot cite a source. Our guide to choosing between prompting, RAG and fine-tuning covers when each fits.
RAG instead changes what the model is shown: the system finds passages relevant to the question and passes both to the model. Update the documents and re-index them, and the answers change too.
How it works, in two stages
A typical RAG system has two parts: one prepares your documents in advance, the other runs for each question. (Some systems instead query an existing search engine or let the model search repeatedly; the principle is the same.)
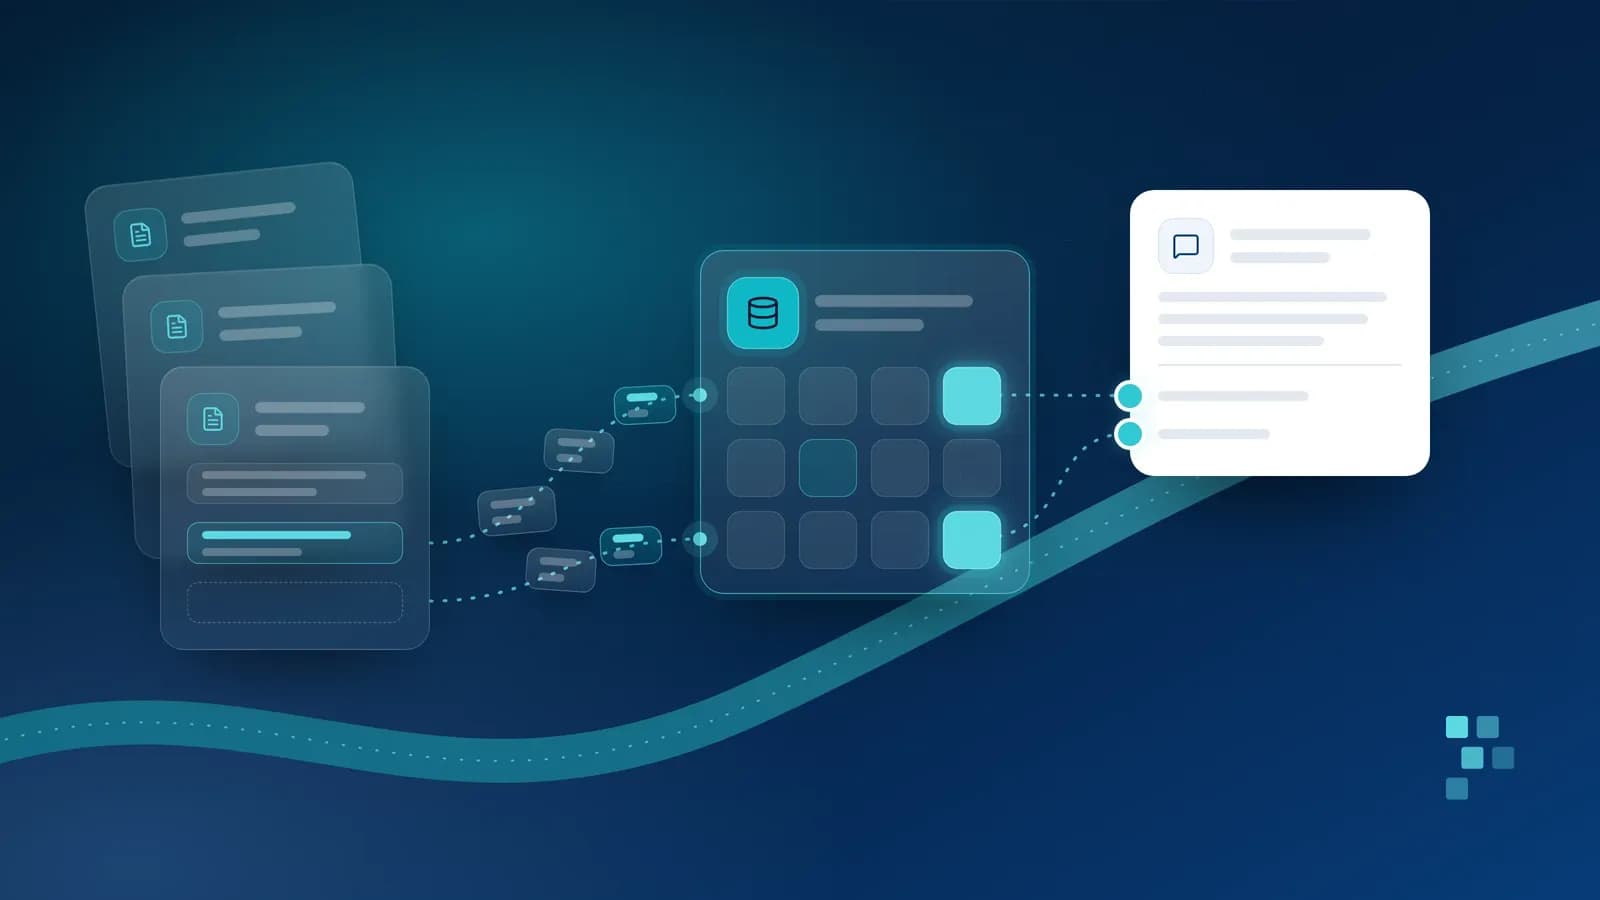
Documents are indexed in advance; each question retrieves passages from that index, and the answer cites them.
Before anyone asks: building the index
Collect and clean the documents: convert them to text (scanned pages need OCR, optical character recognition), strip repeated headers and footers, and drop outdated copies.
Split them into chunks: short passages that each make sense on their own, ideally split along the document's headings.
Create embeddings: lists of numbers, produced by a model trained for the purpose, that roughly capture what each passage is about. Passages with similar meanings get lists that sit close together mathematically, even when worded differently.
Store them in a search index with metadata (source, date, owner, department) and the original document's access permissions.
When someone asks: retrieve, then answer
Retrieve the most relevant passages. Many systems combine keyword search, good at exact terms such as product codes, with semantic search, which turns the question into an embedding and finds passages with similar meaning, so a question about taking holiday into next year can find a section headed “Carrying over annual leave”.
Build a prompt (the text sent to the model) from instructions, the retrieved passages and the question, telling the model to answer only from those passages.
Generate an answer that cites its sources, so the reader can check the original.
Decline when nothing fits. Semantic search always returns its closest matches, even irrelevant ones, so the system needs a relevance cutoff and instructions to decline and refer to a person. Neither is foolproof, so test it.
Citations make checking easier but do not guarantee accuracy: a model can misread a passage, or cite one that does not support what it says.
What decides the quality of the answers
It is tempting to focus on the language model, but its answers can only be as good as the passages it is given. Quality depends heavily on everything around it:
Source quality and freshness. If the documents are wrong, duplicated or out of date, so are the answers. Each collection needs an owner who keeps it current.
Chunking. Too small, and a chunk loses context, such as a sentence about “the table below”; too large, and the relevant sentence is buried in unrelated text.
Search method. The embedding model, combining keyword and semantic search, and re-ranking top results with a second model that checks relevance more closely can matter as much as the language model.
Metadata. Dates, versions and departments let the system filter, say to the current policy for the right site, and let answers name the version used.
Permission filtering. Apply the asker's permissions in the search itself, before anything reaches the model; telling the model to keep something confidential is not a security control. Keep permissions in step with the source systems, so search reflects revoked access and deleted documents promptly, not at the next re-index. The index and the passages sent to the model are copies of your documents (even embeddings can be partly turned back into text); our guide to keeping your data private when you use AI covers how to protect them.
Evaluation. Test retrieval and answers separately: for real questions, did the right passages come back, and is each answer correct, supported by them and properly cited? See our guide to evaluating AI features.
An answer can only be as good as the passages the search finds.
Where RAG goes wrong
Relevant passages are missed
The answer exists but search misses it: the question uses different words, the key fact is split across two chunks, or answering means counting across a whole collection (“How many of our contracts renew next quarter?”). When retrieval misses, clear instructions make the model more likely to decline, but not certain to: it may answer from its general training or stretch a loosely related passage to fit. Answers built on plausible but wrong passages, such as another site's policy, are hardest to spot, so include questions the assistant should decline in the test set.
Outdated or conflicting documents
If last year's and this year's versions of a policy are both indexed, the assistant may quote the wrong one or blend the two. Retire old versions, record versions in the metadata, and have the assistant flag disagreements between sources rather than silently pick one.
Instructions hidden inside documents
A document can contain text written to manipulate the model, such as a line telling it to ignore its rules. This is known as indirect prompt injection, and the risk is greatest with content that people outside a small trusted group can write: emails, web pages and uploads, but also shared wikis or tickets. No known technique makes a model reliably ignore such instructions, so limit the damage. Indexing trusted sources and keeping retrieved text separated from the system's instructions help, but guarantee nothing. Even an answer-only assistant can be made to give wrong answers or malicious links, or to leak data by hiding it in the address of an image or link that the chat window loads, so block external images and link previews in answers. Require a person to confirm before the assistant sends a message or changes a record.
When RAG fits, and when something else is better
RAG fits when knowledge lives in a sizeable, changing collection of text, questions can be answered from a few passages, and people need to see sources, as with staff handbooks, IT help articles or policy libraries. Other problems suit other approaches:
Questions about totals, counts and records, such as a customer's order history, are better answered by querying the database, perhaps with a language model writing the query, run through a read-only account limited to what the asker may see.
A small, stable set of facts can simply go in the prompt. Many current models accept very long prompts, so this goes further than you might expect, though cost, speed and accuracy suffer as prompts grow.
Tasks such as booking an appointment or updating a record need integration with your systems and careful controls, as our guide to AI agents explains.
Many systems combine several of these approaches with RAG.
Where to start
Choose one collection with a clear owner and real audience, such as HR policies.
Tidy it: remove duplicates and outdated versions, and give each document an owner and review date.
Write test questions with expected answers and sources, including some the assistant should decline.
Build permissions in from the start, matching the source systems' access rules and updating them whenever those rules change.
Pilot with a small group and make wrong answers easy to flag.
Plan upkeep: re-index when documents or permissions change, and grow the test set with the collection.
A RAG assistant is a small service, not a one-off build: it needs owners, updates and monitoring. If you are considering one, our AI solutions and automation team can help scope the collection, safeguards and evaluation before anything is built.
Better prompts, retrieval, fine-tuning or tools? A practical guide to working out what your AI feature is missing, and choosing the simplest change that fixes it.
AI features run on your data. How to classify it, trace where it goes, choose where the model runs and put simple controls in place before launch, so you keep personal and business data under your control.
A demo shows an AI feature on a good day. Here is a practical way to test it on real cases, agree what good looks like, and keep checking once it is live.
Read the article
Let's build what's next.
Tell us about your project and we will come back with a clear next step.