Large language models now sit behind chat assistants, writing aids and a growing number of business tools. Most explanations are either too technical or too breathless to help with a practical decision.
What a large language model is
A large language model (LLM) is an AI system trained on very large amounts of text to predict what comes next. The model itself does not look answers up in a database, although some applications add a search step that does. What it learns is held in a very large number of numerical settings, called parameters.
Models do not read whole words. They split text into tokens: short pieces that may be a common word, part of a longer word or a punctuation mark. Everything a model reads and writes is a sequence of tokens. Many models also accept images or audio, converted into tokens in a similar way.
Training happens in stages. First, the model is shown huge quantities of text, such as web pages, books and code, and its parameters are repeatedly adjusted to predict the next token better. Along the way it picks up grammar, style and a broad but imperfect store of general knowledge. It is then tuned on examples of instructions and good responses, with feedback from human reviewers, other AI models or automated checks, so that it follows requests and declines some harmful ones instead of simply continuing the text.
How a model writes an answer, one token at a time
When you send a prompt (the instructions and text you give the model), it is split into tokens and passed through the model. The result is not a sentence but a set of probabilities: for every possible next token, how likely it is. Given Thank you for your, for example, message, email and patience might all score as likely.
One token is chosen and added to the text, and the process runs again. A long reply is built by repeating this step until the model produces a token that signals it has finished or a length limit is reached.
The choice at each step usually involves some controlled randomness, called sampling, which is why the same question can produce different answers on different runs. A setting usually called temperature reduces the randomness. That makes answers more consistent, though not necessarily more correct, and even at its lowest the same request can occasionally produce different wording.
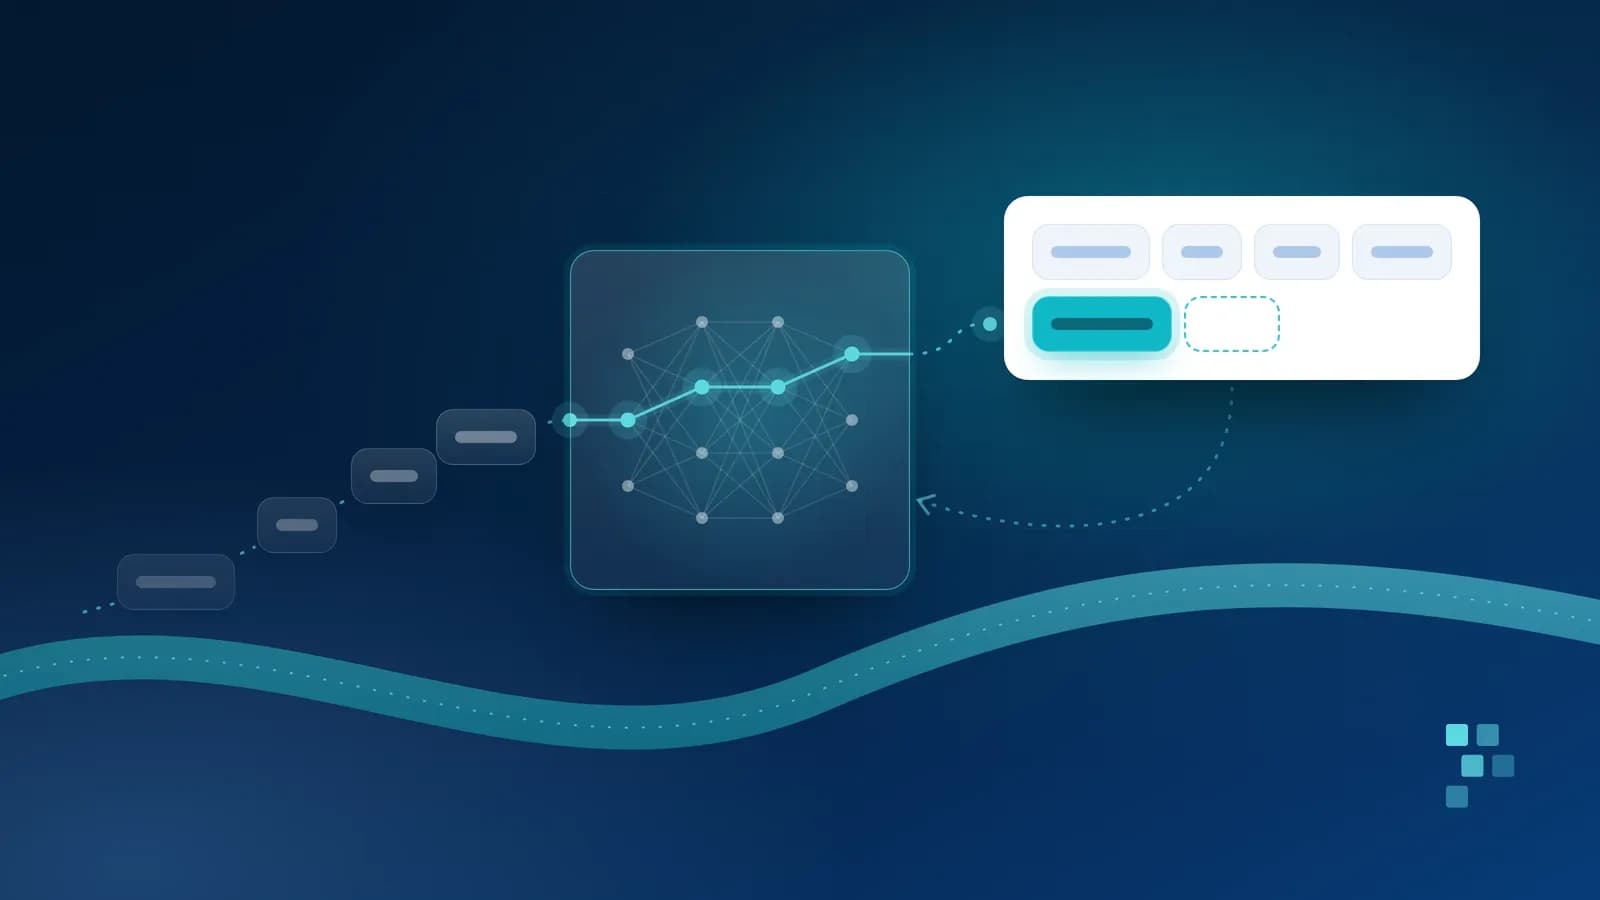
A simplified view of generation: the model scores the possible next tokens, one is chosen and added to the text, and the process repeats.
What the model can see, and what it cannot know
Two limits shape what a model can do. The first is the context window: the maximum amount of text, measured in tokens, that the model can take into account at once. It covers your instructions, any documents, the conversation so far and the answer being written. Anything outside it is not seen, and in a long conversation an application may drop or condense earlier messages to make room. Even inside the window, details in a very long input, especially in the middle, are more easily missed, so supplying the few relevant passages usually works better than pasting in everything.
Because the model sees only what is in the window, it does not remember past conversations by itself; any memory comes from the application sending earlier messages or stored notes back in. That does not mean your data is discarded: depending on the service and its settings, the provider may store conversations, have staff review them or use them to train future models. Check this before sharing anything confidential.
The second limit is the training cutoff: the point after which no new text was included in training. The model itself knows nothing about later events, and often little about the months just before the cutoff. Nor does it know your organisation's private information, such as your price list or last week's meeting notes. Either reaches it only when the application puts it in front of the model, for example through a web search or documents you supply. Supplying the right documents with each question is the idea behind retrieval-augmented generation (RAG), covered in our guide to RAG.
Fluent is not the same as correct
Because a language model is trained to produce likely text, it writes fluently whether or not it has the facts. When the information is missing, it can still produce a confident, well-formed answer that is wrong: an invented reference, a policy clause that does not exist, a date that is slightly off. These errors are usually called hallucinations. Errors also happen when the right information is in front of it: a summary can leave out a key exception or misstate a figure from its source. Such mistakes can be reduced but not reliably eliminated, so any system built on a language model should assume that some answers will be wrong.
Three practices reduce the risk:
Grounding in sources: give the model the relevant documents, ask it to answer only from them and to point to the passages it used. Those citations can themselves be wrong, so spot-check that each passage says what the answer claims.
Tools: let the model hand exact work, such as a calculation, a database lookup or a booking, to software built for it rather than estimating. Give each tool only the access it needs (read-only where possible), and have a person confirm any step that is hard to undo, such as sending messages, spending money, deleting data or changing records about people: text hidden in a document or email can try to steer the model into misusing a tool, an attack known as prompt injection. Our guide to AI agents covers these safeguards.
Human review: have a person check outputs before they reach customers or records, with closer review where mistakes are costly.
Where language models fit, and where they do not
Good fits share two traits: the task is mainly about language, and a person can check the result before it matters.
Good fits are language tasks whose results a person can check; poor fits need exact answers or someone accountable for the outcome.
Good fits
Drafting: first versions of emails, reports or lesson outlines for a person to edit.
Summarising: condensing long documents, meeting notes or feedback that you supply. Check names, figures and exceptions against the original before relying on it.
Classifying: sorting incoming messages into categories so they reach the right team.
Rewriting: changing tone, length or reading level, such as turning a policy into a plain-language notice.
Poor fits
Unsourced facts: questions that need an accurate answer with no documents to draw on, especially on legal, medical or financial matters.
Exact calculation without tools: models can make arithmetic mistakes, especially over many steps. Let a calculator or spreadsheet do the sums.
Decisions that need accountability: hiring, admissions, credit, clinical or disciplinary decisions. Models can reflect biases in their training data and cannot answer for an outcome. They can assist, but a person should decide, reviewing each case properly rather than approving the model's suggestion by default. Using AI in these decisions is regulated in many places, for example under data-protection law and the EU AI Act, so take legal advice before using it even in a supporting role.
A checklist for using language models at work
Start with a task, not the technology: one piece of language-heavy work where a good first draft would save real time.
Decide what good looks like, and test on real examples, including awkward ones, rather than trusting a demo. Our guide to evaluating AI features explains how.
Supply the sources and use tools for exact work: give the model your own policies, prices or records, and let a calculator or system of record handle sums and lookups. Give those tools the narrowest access they need, and confirm any action that is hard to undo. Our guide to prompting, RAG or fine-tuning helps you choose between them.
Protect data. Use only approved tools for personal or confidential information, and check where the data goes, how long it is kept and whether it is used to train models. See keeping your data private when you use AI.
Keep a person accountable. Match review to the cost of a mistake, and make it easy for staff to flag and correct errors.
Be open about it. Tell staff, and where relevant customers, parents or patients, where AI is used and how to reach a person.
Used this way, a language model is a capable assistant for drafting, summarising and sorting, with people checking what matters. If you are weighing where one could help, our AI solutions and automation team starts with one well-defined task and a measurable definition of success.
Retrieval-augmented generation lets an AI assistant answer from your organisation's own documents and show its sources. How it works, what decides its quality, where it fails and when it fits.
Better prompts, retrieval, fine-tuning or tools? A practical guide to working out what your AI feature is missing, and choosing the simplest change that fixes it.
What AI agents are, how they differ from chatbots and rule-based automation, which tasks suit them today, and the guardrails they need before they act for you.
Read the article
Let's build what's next.
Tell us about your project and we will come back with a clear next step.