Invoices, forms and records are often still re-keyed by hand. How document AI turns them into structured data, and how to make the results accurate enough to trust.
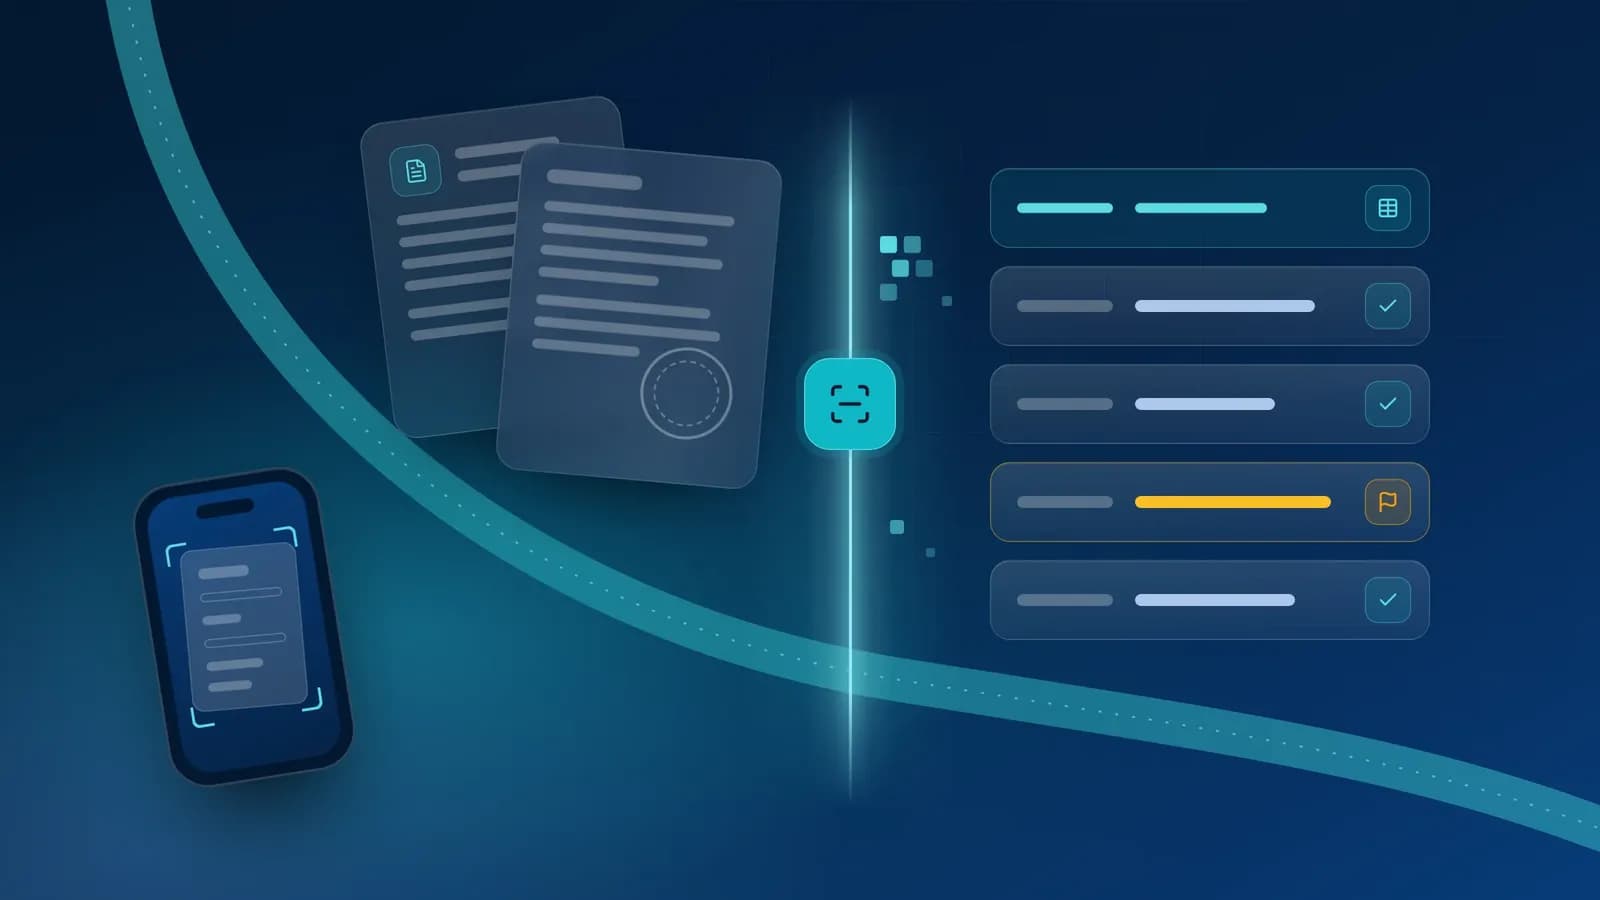
An invoice arrives as a PDF. A parent hands in a printed admission form. Someone then types each detail into another system. Document AI turns such documents into structured data: named fields, such as an invoice number, date and total, that another system can store and check.
The cost of re-keying documents by hand
Many organisations already hold the data they need in PDFs, scans, photos and emails that software cannot use directly, so people re-key it. Re-keying is slow and tedious, and introduces errors, such as a transposed digit, that spread into payments and records where they are hard to find.
How document AI turns a page into data
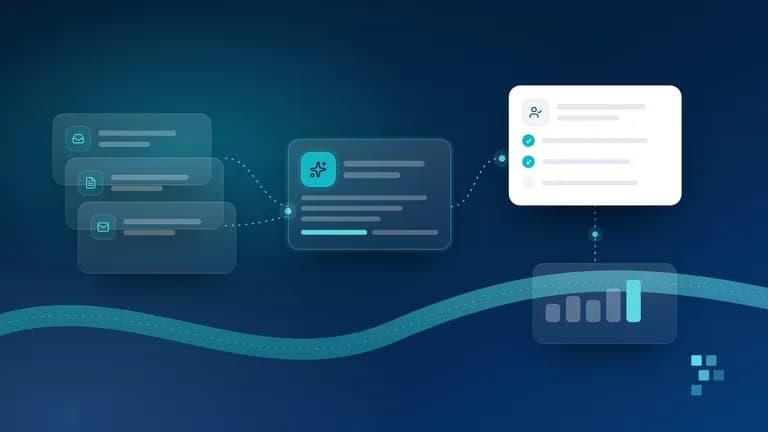
A reliable system is not one clever model but a pipeline: steps that each do one checkable job.
Capture. Collect documents from email, uploads, scanners or a phone camera, and keep each original.
Read text and layout. If a PDF already contains text, read it directly; for scans and photos, optical character recognition (OCR) turns the image into text. Tools also capture layout, such as tables and which label goes with which value. Some multimodal language models read the page image directly, combining this step with extraction.
Classify. Decide what each document is, such as an invoice or an admission form, since each type has its own fields, and where one ends and the next begins when a file holds several.
Extract fields. Pull out the values your system needs, such as invoice number, date and total.
Validate. Check formats, arithmetic and agreement with your records.
Route uncertain fields to a person. Fields that fail a check or have low confidence go to a reviewer, alongside their source on the page.
Integrate. Send confirmed data to your accounts or records system through its API (the interface one system offers another).
A document AI pipeline: each step does one job, and fields that fail a check or have low confidence go to a person before they reach your system.
Three ways to extract fields
Many systems combine these approaches.
Rules and templates suit fixed layouts, such as your own forms. They are cheap, predictable and easy to explain, but break when a supplier redesigns its invoice.
Specialised extraction models are trained on many examples of a document type and handle varied layouts better. Ready-made ones cover common types such as invoices and receipts; custom ones need your own labelled examples, and retraining as requirements change.
Language models can fill in a defined set of fields, often with few or no examples. They are flexible, but can return a plausible value that is not on the page or quietly "correct" one that is, and rarely give a dependable confidence score, so their output needs the same checks.
Validation is what makes the output trustworthy
Many extraction tools give each value a confidence score, a number showing how sure the tool is. Scores are not always well calibrated, and a model can be confidently wrong, so set the review threshold from results on your own documents and add independent checks.
Strong checks use what you already know: formats can be tested, arithmetic recomputed and values compared with your records, as in this example for supplier invoices.
An example of field-level checks on an invoice: the failed total check sends the total, and the amounts it is calculated from, to a person.
When a check fails, the system should not guess. It sends the affected fields, not necessarily the whole document, to a person, shows them the relevant part of the page and records the correction. Corrections help improve rules, prompts or models, and show where the system struggles.
The aim is not a system that is never wrong, but one that knows when to ask.
Measuring accuracy per field and per document type
A single headline accuracy figure hides weak fields and difficult senders.
Take a sample of real documents, faded scans and unusual layouts included, with enough of each type to be meaningful, and record every field's correct value by hand. Keep it apart from documents used to write rules or prompts or to train models, or the results will flatter the system. Then measure:
Field accuracy, per field and document type: how often the extracted value matches the correct one, after agreed normalisation of dates and spacing.
Errors that get through: how often a wrong value passes every check and reaches your system, where the real cost lies.
False alarms: how often a correct value is sent to review. These, and the time each review takes, drive review cost.
Straight-through rate: the share of documents that need no human touch.
Set targets field by field, by what an error costs. For example, you might tolerate a slip in a free-text description but require every amount and bank account number to be confirmed by a check or a person. Those checks show that a value was read correctly, not that the document is genuine, so treat new or changed bank details as a possible fraud signal and verify them with the supplier using contact details you already hold, never those on the invoice. Keep measuring after launch, as templates and document types change. Our guide to evaluating AI features covers maintaining such a test set.
Handling layouts, handwriting, languages and poor scans
Layouts. Every supplier designs its invoices differently. Models that use where text sits, not just what it says, usually cope better than fixed templates, but test your main senders separately.
Handwriting. Handwriting is usually read less accurately than print. Boxed fields, online forms and reviewing handwritten fields by default all help.
Languages. One page may mix scripts, such as English headings with names in a regional script, so check that every step supports them. Accuracy can differ by language, script and handwriting style: measure each, and check that errors and delays do not fall harder on some groups of people.
Poor scans. Shadows, skew, low resolution and stamps over text reduce accuracy. Clean-up helps; guidance at capture helps more, as a retake costs less than a correction.
Privacy, security and retention
Documents often hold sensitive data: bank details on invoices, health information in referrals, children's details on admission forms. Protect the pipeline like the systems it feeds.
Decide where processing happens: your own infrastructure, your cloud account or an external service. For an external service, ask the provider the questions in our privacy guide (linked below), including how long it keeps documents and logs, and sign a data processing agreement.
Encrypt documents in transit and at rest, limit who can see originals and review queues, and log who accessed what.
Treat every incoming document as untrusted and scan uploads for malware. Text in a document, even text hidden in a PDF, can try to steer a language model into, say, reporting a different bank account number: an attack called prompt injection (see our guide to AI agents). Never let extraction alone approve a payment or change master data, such as a supplier's bank details, and check key fields against your own records.
Keep personal data out of application logs. A test set of real documents is just as sensitive: mask it where that does not spoil the test, and otherwise protect it like the originals, including copies shared with a vendor for a pilot.
Keep originals, extracted data and correction records only as long as law and policy require, then delete every copy, including in temporary storage, review tools and providers' systems, and let backups expire on a known schedule.
Data-protection laws such as the EU General Data Protection Regulation (GDPR) and India's Digital Personal Data Protection Act, 2023 apply to personal data in documents, including paper records once scanned. Take legal advice on your obligations; our guide to keeping your data private when you use AI covers the practical side.
Pick one document type that arrives in volume, is re-keyed today and feeds one system, such as supplier invoices into your accounts.
List the fields that system needs, and what an error in each would cost.
Build a test set from recent documents, messy ones included, and add validation and human review from day one.
Run it alongside the manual process; switch over only when field-by-field results support it.
Connect it to that system through a monitored integration that reconciles what was sent.
If you have a document-heavy process in mind, our AI solutions and automation team starts by testing the idea on a sample of your real documents, and our API integration work connects the results to your systems with monitoring and reconciliation.
A demo shows an AI feature on a good day. Here is a practical way to test it on real cases, agree what good looks like, and keep checking once it is live.
Most AI value in operations comes from a few well-chosen, well-measured automations. A four-step method to find the first one and prove it works, with a worked example.
AI features run on your data. How to classify it, trace where it goes, choose where the model runs and put simple controls in place before launch, so you keep personal and business data under your control.
Read the article
Let's build what's next.
Tell us about your project and we will come back with a clear next step.